9. Search
This chapter discusses how exploration for search is used for solving Gecode models. Exploration defines a strategy how to explore parts of the search tree and how to possibly modify the tree’s shape during exploration (for example, during branch-and-bound best solution search by adding new constraints). This chapter restricts itself to simple search engines to find solutions, Gist as an interactive and graphical search engine is discussed in Gist.
Overview. Hybrid recomputation explains how search in Gecode makes use of hybrid recomputation and why it is efficient. Even though this section does not belong to the basic reading material, you are highly encouraged to read it.
Parallel search explains how parallel search can be used in Gecode and what can be expected of parallel search in principle. How search engines can be used is explained in Search engines. Restart-based search is discussed in Restart-based search and portfolio-based search is discussed in Portfolio search. This is followed by a discussion in No-goods from restarts how no-goods from restarts can be used. Tracing search describes how the execution of search engines can be traced and Using the CPProfiler how the CPProfiler can be used for tracing during search.
Note that the same conventions hold as in Integer and Boolean variables and constraints.
9.1. Hybrid recomputation
A central requirement for search is that it can return to previous states: as spaces constitute nodes of the search tree, a previous state is nothing but a space. Returning to a previous space might be necessary because an alternative suggested by a branching did not lead to a solution, or even if a solution has been found more solutions might be requested. As propagation and branching change spaces, provisions must be taken that search can actually return to a previous space, or an equivalent version of that space.
Two space are equivalent if propagation and branching and hence search behave exactly the same on both spaces. Equivalent spaces can be different, for example, they contain different yet equivalent propagators, or are allocated at a different memory area.
Gecode employs a hybrid of two techniques for restoring spaces: recomputation and cloning.
If you want to know how search engines can be programmed in Gecode, please consult Programming search engines.
9.1.1. Cloning
Cloning creates a clone of a space (this is supported by the virtual copy member function as discussed in Getting started). A clone and the original space are of course equivalent. Restoration with cloning is straightforward: before following a particular alternative during search, a clone of the space is made and used later if necessary.
Remember Do not use the copy constructor directly. To create a clone of a Space the clone member function should be called, not the copy function nor the copy constructor.
9.1.2. Recomputation
Recomputation remembers what has happened during branching: rather than storing an entire clone of a space just enough information to redo the effect of a brancher is stored. The information stored is called a choice in Gecode. Redoing the effect is called to commit a space: given a space and a choice committing re-executes the brancher as described by the choice and the alternative to be explored (for example, left or right).
Consider the following part of a model, which constrains both the sum and the product of x[0] and x[1] to be equal to x[2]:
IntVarArray x(home, 3, 1, 6);
rel(home, x[0] + x[1] == x[2]);
mult(home, x[0], x[1], x[2]);
branch(home, x, INT_VAR_NONE(), INT_VAL_MIN());
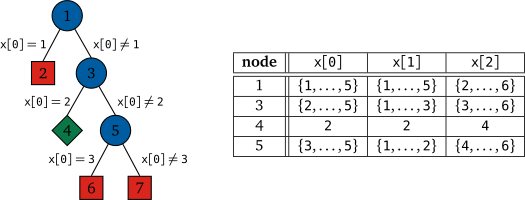
Figure 9.1 Example search tree
The corresponding search tree is shown in Figure 9.1. A red box corresponds to a failed node, a green diamond to a solution, and a blue circle to a choice node (a node that has a not-yet finished brancher left). An example choice for node 3 is \(\left(\mathtt{x[0]} = \mathtt 2\right) \vee \left(\mathtt{x[0]} \neq \mathtt 2\right)\) where the left alternative (or the \(0\)-th alternative) is \(\mathtt{x[0]} = \mathtt 2\) and the right alternative (\(1\)-st alternative) is \(\mathtt{x[0]} \neq \mathtt 2\). Committing a space for node 3 to the \(1\)-st alternative posts the constraint \(\mathtt{x[0]} \neq \mathtt 2\).
More precisely, a choice does not store the actual variables but the position among the variables of the brancher (storing 0 rather than x[0]). By that, a choice can be used with an equivalent yet different space. This is essential as the space used during recomputation will be different from the space for which the choice has been created.
9.1.3. Hybrid recomputation
The hybrid of recomputation and cloning works as follows. For each new choice node, a choice is stored. Then, every now and then search also stores a clone of a space (say, every eight steps). Now, restoring a space at a certain position in the search tree traverses the path in the tree upwards until a clone \(c\) is found on the path. Then recomputation creates a clone \(c'\) of \(c\) (in certain cases, recomputation might use \(c\) directly as an optimization). Then all choices on the path are committed on \(c'\) yielding an equivalent space.
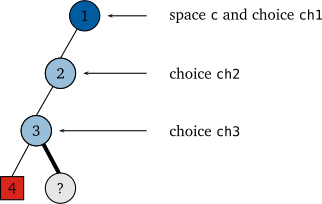
Figure 9.2 Hybrid recomputation
To recompute the node ? for the example shown in Figure 9.2, the following operations are executed:
Space* s = c->clone();
s->commit(ch1, 0);
s->commit(ch2, 0);
s->commit(ch3, 1);
9.1.4. Why recomputation is almost for free
An absolutely fundamental property of the above hybrid is that an equivalent space is computed without performing any constraint propagation! Remember: committing just reposts constraints but does not perform constraint propagation.
Reconsider the example from Figure 9.2. Search has just failed at node 4 and must compute a space for node ?.
Suppose that only cloning but no recomputation is used. Then, a clone of the space for node 3 is created (from the clone that is stored in node 3) and that clone is committed to the first alternative of \(\mathtt{d3}\) (this corresponds to the slightly thicker edge in Figure 9.2). After that, constraint propagation is performed (by executing the status() function of a space, see also Propagation is explicit) to find out if and how search must continue. That is: there is one clone operation, one commit operation, and one status operation to perform constraint propagation.
With hybrid recomputation, one clone operation, three commit operations, and one status operation to perform constraint propagation are needed (as shown above). The good news is that commit operations are very cheap (most often, just modifying a single variable or posting a constraint). What is essential is that in both cases only a single status operation is executed. Hence, the cost for constraint propagation during hybrid recomputation turns out to be not much higher than the cost without recomputation.
For hybrid recomputation, some additional propagation might have to be done compared to cloning. As it turns out, the additional cost is rather small. This is due to the fact that constraint propagation executes all propagators that might be able to remove values for variables until no more propagation is possible (a fixpoint for the propagators is computed). Due to the approximative nature of “might be able to remove values” the additional propagation tends to show only a very small increase in runtime.
9.1.5. Adaptive recomputation
Consider the case that a search engine finds a failed node. That means that some brancher has made an erroneous decision and now search has to recover from that decision. It is quite likely that not only the last decision is wrong but that the decision that lead to failure is somewhere higher up in the search tree. With other words, it is quite likely that search following a depth-first left-most strategy must explore an entire failed subtree to recover from the erroneous decision. In that case it would be better for hybrid recomputation if there was a clone close to the failed node rather than far away.
To optimize recomputation in this example scenario, Gecode uses adaptive recomputation: if a node must be recomputed, adaptive recomputation creates an additional clone in the middle of the recomputation path. A clone created during adaptive recomputation is likely to be a good investment. Most likely, an entire failed subtree will be explored. Hence, the clone will be reused several times for reducing the amount of constraint propagation during recomputation.
More information about search based on recomputation (although not using choices) can be found in [47]. Search using choices has been inspired by batch recomputation [12] and decomposition-based search [36]. For an empirical evaluation of different techniques for search, see [42].
9.1.6. Controlling recomputation
Hybrid and adaptive recomputation can be easily controlled by two integers \(c_d\) (commit distance) and \(a_d\) (adaptive distance). The value for \(c_d\) controls how many clones are created during exploration: a search engine creates clones during exploration to ensure that recomputation executes at most \(c_d\) commit operations. The value for \(a_d\) controls adaptive recomputation: only if the clone for recomputation is more than \(a_d\) commit operations away from the node to be recomputed, adaptive recomputation is used.
Values for \(c_d\) and \(a_d\) are used to configure the behavior of search engines using hybrid and adaptive recomputation, see more in the next Section.
The number of commit operations as distance measure is approximately the same as the length of a path in the search tree. It is only an approximation as search engines use additional techniques to avoid some unused clone and commit operations.
9.2. Parallel search
Parallel search has but one motivation: try to make search more efficient by employing several threads (or workers) to explore different parts of the search tree in parallel.
Gecode uses a standard work-stealing architecture for parallel search: initially, all work (the entire search tree to be explored) is given to a single worker for exploration, making the worker busy. All other workers are initially idle, and try to steal work from a busy worker. Stealing work means that part of the search tree is given from a busy worker to an idle worker such that the idle worker can become busy itself. If a busy worker becomes idle, it tries to steal new work from a busy worker.
As work-stealing is indeterministic (depending on how threads are scheduled, machine load, and other factors), the work that is stolen varies over different runs for the very same problem: an idle worker could potentially steal different subtrees from different busy workers. As different subtrees contain different solutions, it is indeterministic which solution is found first.
When using parallel search one needs to take the following facts into account (note that some facts are not particular to parallel search, check Tip 9.1: they are just more likely to occur):
The order in which solutions are found might be different compared to the order in which sequential search finds solutions. Likewise, the order in which solutions are found might differ from one parallel search to the next. This is just a direct consequence of the indeterministic nature of parallel search.
Naturally, the amount of search needed to find a first solution might differ both from sequential search and among different parallel searches. Note that this might actually lead to super-linear speedup (for \(n\) workers, the time to find a first solution is less than \(1/n\) the time of sequential search) or also to real slowdown.
For best solution search, the number of solutions until a best solution is found as well as the solutions found are indeterministic. First, any better solution is legal (it does not matter which one) and different runs will sometimes be lucky (or not so lucky) to find a good solution rather quickly. Second, as a better solution prunes the remaining search space the size of the search space depends crucially on how quickly good solutions are found.
As a corollary to the above items, the deviation in runtime and number of nodes explored for parallel search can be quite high for different runs of the same problem.
Parallel search needs more memory. As a rule of thumb, the amount of memory needed scales linearly with the number of workers used.
For parallel search to deliver some speedup, the search tree must be sufficiently large. Otherwise, not all threads might be able to find work and idle threads might slow down busy threads by the overhead of unsuccessful work-stealing.
From all the facts listed, it should be clear that for depth-first left-most search for just a single solution it is notoriously difficult to obtain consistent speedup. If the heuristic is very good (there are almost no failures), sequential left-most depth-first search is optimal in exploring the single path to the first solution. Hence, all additional work will be wasted and the work-stealing overhead might slow down the otherwise optimal search.
Parallel search is controlled by the number of threads (or workers) used for search. If a single worker is requested, sequential search is used. The number of threads to be used for search is controlled by the search options passed to a search engine, see the following section for details.
Gecode also provides parallel portfolio search which is discussed in Portfolio search.
9.3. Search engines
Important
Do not forget to add
#include <gecode/search.hh>
to your program when you want to use search engines.
member |
type |
meaning |
|---|---|---|
|
|
propagators executed |
|
|
failed nodes explored |
|
|
nodes explored |
|
|
restarts performed |
|
|
no-goods generated |
|
|
maximal depth of explored tree |
Figure 9.5 Search statistics (partial)
All search engines in Gecode are parametric (are templates) with respect to a subclass T of Space (for example, SendMoreMoney in A first Gecode model). Moreover, all search engines share the same interface:
The search engine is initialized by a constructor taking a pointer to an instance of the space subclass
Tas argument. By default, the search engine takes a clone of the space passed.This behavior can be changed, as can be other aspects of a search engine, see Search options.
A next solution can be requested by a
next()member function. If no more solutions exist,next()returnsNULL. Otherwise, the engine returns a solution which again is an instance ofT. The client of the search engine is responsible for deleting solutions.A search engine can be asked for statistics information by the
statistics()member function. The function returns an object of type Search::Statistics. The statistics information provided is partially summarized in Figure 9.5 (see Restart-based search for the meaning ofrestartand No-goods from restarts for the meaning ofnogood).A search engine can be queried by
stopped()whether the search engine has been stopped by a stop object. Stop objects are discussed in Stop objects.The destructor deletes all resources used by the search engine.
Note that search engines use pointers to objects rather than references to objects. The reason is that some pointers might be NULL-pointers (for example, if next() fails to find a solution) and that users of search engines have to think about deleting solutions computed by search engines.
Figure 9.6 Available search engines
For each search engine there also exists a convenient shortcut function (of the same name but entirely in lowercase letters) that returns either the first solution or, in the case of best solution search, the last (and hence best) solution. The available search engines are summarized in Figure 9.6.
BAB continues search when a solution is found by adding a constraint (through the constrain() function as discussed in Best solution search) to search for a better solution to all remaining nodes of the search tree.
Note that the version of Gecode (6.4.0) this document corresponds to does not support parallel search for LDS.
9.3.1. Search options
All search engines can take a default option value of type Search::Options when being created. The options are summarized in Figure 9.7. The default values for the options are defined in the namespace Search::Config.
member |
type |
meaning |
|---|---|---|
|
|
number of parallel threads to use |
|
|
commit recomputation distance |
|
|
adaptive recomputation distance |
|
|
whether engine uses a clone when created |
|
|
discrepancy limit (for |
|
|
depth limit for no-good generation |
|
|
number of assets in a portfolio |
|
|
stop object ( |
|
|
cutoff object ( |
|
|
search tracer ( |
Figure 9.7 Search options
The meaning of the values for the search options are straightforward but for threads (cutoff is explained in Restart-based search, assets is explained in Portfolio search, nogoods_limit is explained in No-goods from restarts, and tracer is explained in Tracing search).
Assume that your computer has \(m\) processing units [1] and that the value for threads is \(n\).
If \(n=0\), then \(m\) threads are used (as many as available processing units).
If \(n\geq 1\), then \(n\) threads are used (absolute number of threads to be used).
If \(n\leq -1\), then \(m+n\) threads are used (absolute number of processing units not to be used). For example, when \(n=-6\) and \(m=8\), then \(2\) threads are used.
If \(0<n<1\), then \(n\cdot m\) threads are used (relative number of processing units to be used). For example, when \(n=0.5\) and \(m=8\), then \(4\) threads are used.
If \(-1<n<0\), then \((1+n)\cdot m\) threads are used (relative number of processing units not to be used). For example, when \(n=-0.25\) and \(m=8\), then \(6\) threads are used.
Note that all values are of course rounded and that at least one thread will be used.
9.3.2. Stop objects
A stop object (a subclass of Search::Stop) implements a single virtual member function stop() that takes two arguments, the first of type Search::Statistics and the second of type Search::Options, and returns either true or false. If a stop object is passed to a search engine (by passing it as stop member of a search option), the search engine calls the stop() function of the stop object before every exploration step and passes the current statistics as argument. If the stop() function returns true, the search engine stops its execution.
When a search engine is stopped its next() function returns NULL as solution. To find out whether a search engine has been stopped or whether there are no more solutions, the stopped() member function of a search engine can be used. Search can be resumed by calling next() again after the stop object has been modified (for example, by increasing the node or time limit).
Note that when using several threads for parallel search, each thread checks whether it is stopped independently using the very same stop object. If one thread is stopped, then the entire search engine is stopped.
class |
description |
|---|---|
node limit exceeded |
|
failure limit exceeded |
|
time limit exceeded |
Figure 9.8 Predefined stop objects
Gecode provides several predefined stop objects, see Stop-objects for stopping search. For an overview see Figure 9.8. Objects of these classes can be created conveniently by, for example:
Stop* s = Search::Stop::node(l);
The class Search::Stop also provides similar static functions fail() and time().
9.4. Restart-based search
The idea of restart-based search is to run search with a given cutoff (Gecode uses the number of failures during search as cutoff-measure). When search reaches the cutoff, it is stopped and then restarted with a new and typically increased cutoff.
The whole point of restarting search is that it is not restarted on exactly the same problem but on a modified or re-configured problem. Possible modifications include but are not limited to:
Improved information from the search for branching heuristics such as action (see Selection using action) or AFC (see Selection using accumulated failure count): the now stopped search has gathered some information of which branching can take advantage in the next restart of search.
The next search can use different random numbers that controls branching. A typical strategy would be to use tie-breaking for combining a branching heuristic with a random branching heuristic (see Tie-breaking) and control the degree of randomness by a tie-breaking limit function.
The next search uses an entirely different branching heuristic.
The next search adds so-called no-goods derived from the now stopped search. No-goods are additional constraints that prevent the restarted search to make decisions during search that lead to failure in the stopped search. No-goods are discussed in detail in No-goods from restarts.
The next search “keeps” only a randomly selected part of a previous solution and tries to find a different solution. This is often used for optimization problems and is known as LNS (Large Neighborhood Search) [55]. How restart-based can be used for LNS is discussed in Large Neighborhood Search.
For an example illustrating the effect of restart-based search, see More information. A general overview of restart-based search can be found in [69].
9.4.1. Restart-based search as a meta search engine
Restart-based search in Gecode is implemented as a meta search engine: the meta search engine uses one of the Gecode search engines discussed in Search engines to perform search for each individual restart. The meta engine then controls the engine, the cutoff values, and how the problem is configured before each restart. The interface of the meta search engine in Gecode is exactly the same as the interface of a non-meta search engine. In addition to the restart meta search engine, Gecode offers a portfolio meta search engine which is described in Portfolio search.
The restart meta search engine RBS is parametric with respect to both the script to be solved (a subclass of Space) and the search engine to be used. For example, when we want to use the DFS engine for the script s of class type Script, the meta engine e can be created by (o are mandatory search options, see below):
RBS<Script,DFS> e(s,o);
Now e implements exactly the same interface as the normal engines (that is, next() to request the next solution, statistics() to return the meta engine’s statistic, and stopped() to check whether the meta engine has been stopped).
The meta engine honors all search options as discussed in Search options. If parallel search is requested, the engine used by the meta engine will use the specified number of processing units to perform parallel search. The meta engine requires that the search options specify a Search::Cutoff object defining the cutoff sequence.
Best solution search. Restart-based search can be used for both finding any solution or finding a best solution. For searching for a best solution, the meta engine should be used with the BAB engine, for example as:
RBS<Script,BAB> e(s,o);
The behavior whether the engine performs a restart when a better solution is performed or whether the BAB engine continues to find a better solution with a restart can be controlled as described in Master and slave configuration.
When using restart-based search for finding a best solution it is essential to use the BAB engine when used as part of a portfolio-based search engine, see Mixed portfolios.
Parallel search. The restart-based search engine supports parallel search in that the engine used for performing the restarts can be run in parallel. The number of threads used can be described by the search options passed to the restart-based search engine as described in Parallel search.
9.4.2. Cutoff generators
The meta engine uses a cutoff generator that generates a sequence of cutoff values. A cutoff generator must be implemented by inheriting from the class Search::Cutoff. This abstract class requires that two virtual member functions operator()() and operator++() are implemented, where the first returns the current cutoff value and the second increments to the next cutoff value and returns it. Cutoff values are of type unsigned long long int.
When using the restart meta engine, an instance of a subclass of Search::Cutoff must be passed to the engine by using the search options (see Search options). For example, when s is a space to be solved and c a cutoff generator, then the restart engine can be created by:
Search::Options o;
o.cutoff = c;
RBS<Script,DFS> e(s,o);
Gecode provides some commonly used cutoff generators:
- Geometric.
A geometric cutoff sequence is defined by the scale-factor
sand the baseb. Then, the sequence consists of the cutoff values:\[\mathtt{s}\cdot\mathtt{b}^i\qquad\text{for }i=0,1,2,\ldots \]A cutoff generator
cfor a geometric cutoff sequence with scale-factors(of typeunsigned long long int) and baseb(of typedouble) is created by:Search::Cutoff* c = Search::Cutoff::geometric(s,b);
The generator is implemented by the class Search::CutoffGeometric.
- Luby.
A Luby cutoff sequence is based on the Luby-sequence from [31]. The sequence starts with a
1. The next part of the sequence is the entire previous sequence (only1) with the last value of the previous sequence (1again) doubled. This construction is then repeated, leading to the sequence:\[1,1,2,1,1,2,4,1,1,2,1,1,2,4,8,\ldots \]To be practically useful, the values in the Luby sequence are scaled by multiplying them with a scale-factor
s.A cutoff generator
cfor a Luby cutoff sequence with scale-factors(of typeunsigned long long int) is created by:Search::Cutoff* c = Search::Cutoff::luby(s);
The generator is implemented by the class Search::CutoffLuby.
- Random.
A random cutoff sequence consists of uniformly randomly chosen values between a lower bound
minand an upper boundmax. To focus on rather different values, only values from the set of \(\mathtt n+1\) values:\[\{\mathtt{min}+\lfloor i\cdot(\mathtt{max}-\mathtt{min})/\mathtt{n}\rfloor\mid i=0,\ldots,\mathtt{n}\} \]are chosen randomly.
A cutoff generator
cfor a random sequence with lower boundmin, upper boundmax, and number of valuesn(all of typeunsigned long long int) is created by:Search::Cutoff* c = Search::Cutoff::rnd(seed,min,max,n);
where
seed(of typeunsigned int) defines the seed value for the random number generator used. The generator is implemented by the class Search::CutoffRandom.- Constant.
A constant cutoff sequence is defined by the scale-factor
s. Then, the sequence consists of the cutoff values:\[\mathtt{s},\mathtt{s},\mathtt{s},\ldots \]The generator is implemented by the class Search::CutoffConstant.
A cutoff generator
cfor a constant cutoff sequence with scale-factors(of typeunsigned long long int) is created by:Search::Cutoff* c = Search::Cutoff::constant(s);
- Linear.
A linear cutoff sequence is defined by the scale-factor
s. Then, the sequence consists of the cutoff values:\[1\cdot\mathtt{s},2\cdot\mathtt{s},3\cdot\mathtt{s},\ldots \]A cutoff generator
cfor a linear cutoff sequence with scale-factors(of typeunsigned long long int) is created by:Search::Cutoff* c = Search::Cutoff::linear(s);
The generator is implemented by the class Search::CutoffLinear.
- Append.
An appended cutoff sequence
cfornvalues from the cutoff sequence \(\mathtt{c}_1\) (with values \(k_0,k_1,k_2,\ldots\)) followed by the values from the cutoff sequence \(\mathtt{c}_2\) (with values \(l_0,l_1,l_2,\ldots\)) consists of the following values:\[k_0,k_1,\ldots,k_{\mathtt{n}-2},k_{\mathtt{n}-1},l_0,l_1,l_2,\ldots \]A cutoff generator
cfor an appended cutoff sequence withn(of typeunsigned long long int) values from cutoff generatorc1followed by values from cutoff generatorc2is created by:Search::Cutoff* c = Search::Cutoff::append(c1,n,c2);
The generator is implemented by the class Search::CutoffAppend.
- Merge.
A merged cutoff sequence
cfor values from the cutoff sequence \(\mathtt{c}_1\) (with values \(k_0,k_1,k_2,\ldots\)) merged with the values from the cutoff sequence \(\mathtt{c}_2\) (with values \(l_0,l_1,l_2,\ldots\)) consists of the following values:\[k_0,l_0,k_1,l_1,k_2,l_2,\ldots \]A cutoff generator
cfor a merged cutoff sequence with values from cutoff generatorc1merged with values from cutoff generatorc2is created by:Search::Cutoff* c = Search::Cutoff::merge(c1,c2);
The generator is implemented by the class Search::CutoffMerge.
- Repeat.
A repeated cutoff sequence
cwith repeat factorn(of typeunsigned long long int) for the cutoff sequence \(\mathtt{c}'\) (with values \(k_0,k_1,k_2,\ldots\)) consists of the following values:\[\begin{array}{cccl} \underbrace{k_0,k_0,\ldots,k_0},& \underbrace{k_1,k_1,\ldots,k_1},& \underbrace{k_2,k_2,\ldots,k_2},& \ldots\\ \mbox{\texttt{n} times}& \mbox{\texttt{n} times}& \mbox{\texttt{n} times} \end{array}\]A cutoff generator
cfor a repeated cutoff sequence with repeat factorn(of typeunsigned long long int) and values from the cutoff generatorc1is created by:Search::Cutoff* c = Search::Cutoff::repeat(c1,n);
The generator is implemented by the class Search::CutoffRepeat.
9.4.3. Computing a next solution
When the restart meta engine is asked for a next solution by calling next(), there are three possible scenarios:
next()returns a pointer to a space (which might beNULLin case there are no more solutions or the engine has been stopped). Deleting the space is as with other engines the responsibility of the meta engine’s user.By default, asking the meta engine for another solution will perform a restart. However, this behavior can be changed such that the current cutoff value (minus the failed nodes it took to find the current solution) is used for finding a next solution. For details, see Master and slave configuration.
The meta engine reaches the current cutoff value. It restarts search with the next cutoff value.
The meta engine is stopped by the stop object passed to it. Then
next()returnsNULLandstopped()returnstrue(to be able to distinguish this scenario from the one where there are no more solutions).
9.4.4. Master and slave configuration
The meta engine maintains a master space and each time the meta engine performs a restart, it passes a slave space (a clone of the master space) to the engine. Configuration is as follows: the master is configured, the slave is created as a clone of the master, and then the slave is configured. Initially, when the meta engine starts and creates a first slave space, it also configures the slave space.
More accurately, it leaves the actual configuration to the user: it calls the virtual member function master() on the master space and then calls the virtual member function slave() on the slave space. As mentioned above, the slave() function is also called the first time a slave is created. In that way, by redefining master() and slave() the user can control how master and slave are being configured (this is exactly the same idea how constrain() works for best solution search).
function |
type |
meaning |
|---|---|---|
|
|
type of meta information |
restart-based information |
||
|
|
number of restart |
|
|
number of solutions since last restart |
|
|
number of failures since last restart |
|
|
last solution found (or |
|
|
no-goods recorded from restart |
portfolio information |
||
|
|
number of asset (slave) |
Figure 9.9 Meta information member functions
By default, every space implements the two member functions master() and slave(). Both functions take an argument of class MetaInfo that contains information about the current restart (and also for different assets in a portfolio, see Portfolio search). The class MetaInfo provides the member functions as shown in Figure 9.9.
For a meta information object mi, the function mi.type() returns either MetaInfo::RESTART or MetaInfo::PORTFOLIO. In this section, we are only interested in the functions that are concerned with restart-based search.
The default slave() function does nothing and returns true, indicating that the search in the slave space is going to be complete. This means that if the search in the slave space finishes exhaustively, the meta search will also finish. Returning false instead would indicate that the slave search is incomplete, for example if it only explores a limited neighborhood of the previous solution.
The default master() function does the following (for a restart, that is):
It calls the
constrain()member function with the last solution found as argument (if a solution has already been found).It possibly posts no-goods as explained in No-goods from restarts.
It returns
trueforcing a restart even if a solution has been found. Returningfalseinstead would continue search without a restart.
For example, a class Script can define the member functions as follows:
class Script : public Space {
  ...
  virtual bool master(const MetaInfo& mi) {
    // Configure the master
    ...
    // Whether to restart or not
    return true;
  }
  virtual bool slave(const MetaInfo& mi) {
    // Configure the slave
    ...
    // Search is complete
    return true;
  }
};
virtual bool Space::master(const MetaInfo& mi) {
  switch (mi.type()) {
  // [default master and slave functions:restart-based search]
  // [default master and slave functions:portfolio search]
  default:
    break;
  }
  return true;
}
virtual bool Space::slave(const MetaInfo& mi) {
  return true;
}
The default master() and slave() member functions are shown in Program 9.1. The part of the master() function that is specific for restart-based search is as follows:
    if (mi.last() != NULL)
      constrain(*mi.last());
    mi.nogoods().post(*this);
    return true;
9.4.5. Large Neighborhood Search
The design of restart-based search in Gecode is general enough to support LNS (Large Neighborhood Search) [55]. The idea of LNS is quite simple, where LNS looks for a good solution:
Search finds a first solution where typically preference is given to find a reasonably good solution quickly.
During LNS, a new problem is generated that only keeps part of the so-far best solution (typically, the part to keep is randomly selected). This is often referred to as relaxing the so-far best solution. Then, search tries to find a next and better solution within a given cutoff.
If the cutoff is reached without finding a solution, search can either decide to terminate or randomly retry again.
class Model : public Space {
protected:
  IntVarArray x;
  Rnd r;
public:
  Model(void) : ... {
    // Initialize master
  ...
  }
  void first(void) {
    // Initialize slave for first solution
  ...
  }
  void next(const Model& b) {
    // Initialize slave for next solution
  ...
  }
  ...
  // [model sketch for LNS:slave function]
  virtual bool master(const MetaInfo& mi) {
    ...
  }
};
Program 9.2 sketches a model that supports LNS. The constructor Model() initializes the model with all variables and constraints that are common for finding the first solution as well as for finding further solutions. Note that the model has a random number generator of class Rnd as member r to illustrate that typically some form of randomness is needed for restarting. However, in a real life problem additional data structures might be needed.
The first() function is responsible for posting additional constraints and branchings such that search can find the first solution. The next() function takes the so-far best solution b and posts additional constraints and branchings to find a next and better solution than b. This will typically mean that some but not all variables in the current space are assigned to values as defined by the so-far best solution b or that additional constraints are posted that depend on b.
Both first() and next() are executed on the slave space when the restart-based search engine performs a restart or executes search for the first time. This can be achieved by defining the slave() function as follows. Note how it returns true to indicate that the search is going to be complete until it has found a first solution [2] but false for subsequent restarts, which only explore a neighborhood and are therefore incomplete:
  virtual bool slave(const MetaInfo& mi) {
    if (mi.type() == MetaInfo::RESTART) {
      if (mi.last() == nullptr) {
        first();
        return true;
      } else {
        next(static_cast<const Model&>(*mi.last()));
        return false;
      }
    } else {
      ...
    }
  }
The default master() function as shown in Master and slave configuration is already general enough to support LNS.
Relaxing variable assignments. A typical way to relax a given solution, is to assign some but not all variables before a restart to a value from a previous solution. This is supported by the relax() function for integer, Boolean, set, and float variables.
Assume that x is an array of integer variables in the Model script sketched in Program 9.2. Then, the following next() function:
void next(const Model& b) {
  relax(*this, x, b.x, r, 0.7);
}
relaxes each variable in x with a probability of \(0.7\) (or, with other words: each variable in x would be assigned the value from b.x with a probability of \(0.3\)). The random numbers are drawn from the random number generator r.
The relax() function makes sure that at least one of the variables in x remains unassigned (if needed, the variable to remain unassigned is determined uniformly randomly).
For an example using LNS and the relax() function please consult Placing people on a photo.
9.5. Portfolio search
The idea of portfolio search is to run several copies, where each copy is called an asset or a slave, of the same problem independently where each copy typically uses a different branching heuristic (the copies might of course also differ in how the same problem is modeled). The goal is to increase the likelihood of finding a solution to the problem quickly and hence to increase search robustness.
Portfolio search in Gecode is provided as a meta search engine, for the general idea of a meta search engine, please consult Restart-based search as a meta search engine. For more information on portfolios in constraint programming, see [20].
9.5.1. Simple portfolio search as a meta search engine
Portfolio search is, like restart-based search, implemented as a meta search engine. The meta engine creates one slave search engine per asset of the portfolio and coordinates their execution. The portfolio search engine has two interfaces, a simple one that is very similar to the interfaces of non-meta search engines and of restart-based search engines, and a second interface that is considerably more powerful in that it can mix different types of search engines in one portfolio. The advanced interface is described in Mixed portfolios.
The key parameter for portfolio search is the number of assets. For example, a portfolio engine with four assets can be created by:
Search::Options o;
o.assets = 4;
PBS<Script,DFS> e(s,o);
Here, for each asset an engine of type DFS is created for a clone of the master space s.
Before the clones are created, the master() member function as implemented by the Script class is called. On each clone, the slave() function is called where the slave function is called with information about the number of the asset (ranging from 0 to 3, the number of assets minus one). The following section explains the details of how the master and the slaves are configured, whereas Parallel and sequential portfolios explains how assets of a portfolio are executed sequentially or in parallel.
9.5.2. Master and slave configuration
The master() function provided by a script is called exactly once on the master space from which clones are created for each asset. The purpose of the master() function can be to setup certain aspects of a script specific to portfolio search.
The portfolio-specific part of the default master() function is as follows, the entire master() function is shown in Program 9.1:
    BrancherGroup::all.kill(*this);
    break;
That is, by default all branchers contained in the master space are deleted before the slave spaces are created, for more on killing branchers see Brancher groups. This provides the opportunity to create branchers specific to each asset by the slave() function.
The default slave() function does nothing, in order to be meaningful for portfolio search a user needs to define one. Assume that you have four different variants of your model, each using a different brancher. Then the following slave() function creates branchers specific for each asset:
virtual bool slave(const MetaInfo& mi) {
  if (mi.type() == MetaInfo::PORTFOLIO) {
    switch (mi.asset() & 3) {
    case 0: branch(...); break;
    case 1: branch(...); break;
    case 2: branch(...); break;
    case 3: branch(...); break;
  }
  return true;
}
where the function mi.asset() returns the number of the asset being created. Creating more than four asset for this particular example seems to be not that useful, but in Mixed portfolios we are going to discuss how different search engines can be run in one portfolio. Here one could imagine a portfolio that includes an engine running sequential search together with an engine that runs exactly the same script, however with parallel search using more than one thread. Note that the return value of the slave() function has no meaning for portfolio search (but it has for restart-based search).
For an example using several branchers using different random seeds in a portfolio, see Quasigroup completion.
9.5.3. Parallel and sequential portfolios
Whether the assets in a portfolio are run in parallel or just concurrently is controlled by the number of assets in relation to the number of threads requested. The way how threads are allocated to assets is conservative: there will be never more threads running than requested, possibly at the expense of running fewer assets than requested.
Sequential portfolios. A sequential portfolio consisting of \(n\) assets is executed in a simple round-robin scheme: the first asset is given a certain slice, measured in the number of failures encountered during search for that asset. If a solution is found within this slice, the portfolio search engine reports this solution (as a result of its next() function). If no solution is found, the portfolio engine gives a slice to the second assets, and so on. If the last asset exceeds its slice, search continues with the first asset again.
The size of the slice can be controlled by the options passed to the portfolio engine. For example,
Search::Options o;
o.assets = 3;
o.slice  = 50;
PBS<Script,BAB> e(s,o);
creates a portfolio with three assets, where a slice is \(50\) failures. The default value for a slice is defined in the namespace Search::Config.
Parallel portfolios. If parallel execution is requested (the numbers of threads requested is greater than one, see Search options), a parallel portfolio engine is created where each asset is run in its own thread. For example,
Search::Options o;
o.assets = 3; o.threads = 3;
PBS<Script,DFS> e(s,o);
will create three threads each running a (sequential) depth-first search engine.
As mentioned before, threads are created conservatively. That is,
Search::Options o;
o.assets = 4; o.threads = 2;
PBS<Script,DFS> e(s,o);
creates only two threads for two assets.
If more threads than assets are requested, the remaining threads are passed on to the assets. For example,
Search::Options o;
o.assets = 2; o.threads = 4;
PBS<Script,DFS> e(s,o);
creates a portfolio with assets where each asset is a parallel search engine using two threads. In more detail, requesting \(n\) assets and \(m\) threads and \(m>n\), then for each asset \(\left\lfloor \frac{m}{n} \right\rfloor\) threads are requested.
9.5.4. Mixed portfolios
The interface discussed in the previous section creates only assets where each asset runs the same search engine. This is often not desirable. For example, a common strategy is to mix assets using search with and without restarts.
Therefore a more expressive interface to portfolio search is provided that is based on the idea of search engine builders (SEBs). A search engine builder is defined by its type and is created using search options as input (that is, each engine to be built can have its own search options). Then the portfolio search engine creates an engine as defined by the type and the options of all SEBs passed as arguments. The type of a SEB can be either dfs (depth-first search), lds (limited discrepancy search), bab (branch-and-bound solution search for a best solution), rbs (restart-based search), or pbs (portfolio search). The types dfs, lds, and bab are parametric with respect to a script type (as the engines DFS, LDS, and BAB are) and the rbs and pbs types are parametric with respect to both the script type and the engine type (as the meta engines RBS and PBS are).
Consider the following example: we would like to create a portfolio for the master space master of type Script which consists of the following assets:
A depth-first search engine using two threads; and
Another depth-first search engine using a single thread; and
A restart-based meta engine using a depth-first engine with a single thread and a Luby cutoff sequence with scale factor
10(see Cutoff generators).
The portfolio engine should use one thread for each asset.
The respective portfolio engine can be created as follows:
Search::Options s0, s1, s2;
s0.threads = 2;
s1.threads = 1;
s2.threads = 1;
s2.cutoff  = Search::Cutoff::luby(10);
Search::Options s;
s.threads = 3;
PBS<Script> e(master,
              SEBs({dfs<Script>(s0),
                    dfs<Script>(s1),
                    rbs<Script,DFS>(s2)}),
             s);
Note that the number of assets is defined by the number of SEBs passed as argument and not by s.assets as with the simpler interface. Executing a function such as dfs() in fact creates a new SEB seb that eventually must be deleted by delete seb. When creating a portfolio engine from a SEB, the engine takes care of deleting the SEB.
Best solution search. Whether a portfolio search engine created from SEBs performs best solution search is determined by the SEBs. If the SEBs are created by bab<Script>(), rbs<Script,BAB>(), or pbs<Script,BAB>() then the engine performs best solution search. Mixing best solution search SEBs with non-best solution search SEBs throws an exception of type Search::MixedBest.
9.6. No-goods from restarts
As discussed in Restart-based search, the idea of using restarts effectively is to restart with an improved problem with the hope that search is capable of solving the improved problem. No-goods are constraints that can be learned from the configuration of a depth-first search engine after it has stopped. The no-goods encode failures during search as constraints: after restarting, propagation of the no-goods ensures that decisions that lead to failure are avoided. Note that no-goods are only available from the depth-first search engines DFS and BAB but not from limited discrepancy search LDS.
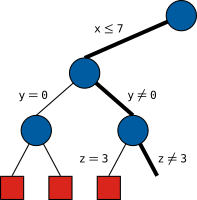
Figure 9.10 Search tree after cutoff \(3\) has been reached
Consider the simple example depicted in Figure 9.10. It shows a search tree that has been explored by the restart-based search engine with a cutoff of \(3\) failures. The thick edges in the tree depict the path that is stored by a search engine using depth-first search (such as DFS or BAB).
What can be immediately derived from this configuration is that the following two constraints (they correspond to conjunctions of alternatives shown in Figure 9.10):
are no-goods: they cannot be satisfied by any solution of the problem (after all, search just proved that). The alternatives in the conjunction are also known as no-good literals.
When restarting search, the negation of the no-goods can be added to the master space as constraints and can be propagated. That is, the following constraints can be added:
or, equivalently, the constraints:
Now assume that when restarting, after some search the constraint \(\mathtt{x}\leq\mathtt{7}\) becomes subsumed. Then, it can be propagated that \(\mathtt{y}\neq\mathtt{0}\). With other words, whenever \(\mathtt{x}\leq\mathtt{7}\) holds, then also \(\mathtt{y}\neq\mathtt{0}\) holds. This explains (if you know about resolution, you have figured out that one already anyway) that it is equivalent to use the following two constraints:
No-goods from restarts in Gecode follow the idea from [28], however the implementation differs. Moreover, the no-good literals used in Gecode can be arbitrary constraints and hence generalize the ideas from [24] and [28]. Also no-goods in Gecode support choices of arbitrary arity and are not restricted to binary choices. For more details, see Advanced topics and in particular Supporting no-goods.
Generating and posting no-goods. When the restart-based search engine reaches the current cutoff limit or finds a solution it calls the master() member function as discussed in the previous section.
From the argument of class MetaInfo that is passed to the master() function a no-good of class NoGoods can be retrieved by calling the nogoods() function. A no-good has really only post() as its single important member function. The following master() function posts all constraints corresponding to the no-goods that can be derived from a restart (this is also the default master() function defined by the class Space, see also Master and slave configuration):
virtual bool master(const MetaInfo& mi) {
  ...
  mi.nogoods().post(*this);
  ...
}
In order to post no-goods it must be enabled that a search engine maintains its internal state such that no-goods can be extracted. This is done by setting the no-goods depth limit (the member nogoods_limit of a search option of type unsigned int) to a value larger than zero. The value of nogoods_limit describes to which depth limit no-goods should be extracted from the path of the search tree maintained by the search engine. For example, the following code (it assumes that c refers to a cutoff object):
Search::Options o;
o.cutoff = c;
o.nogoods_limit = 128;
RBS<Script,DFS> e(s,o);
instructs the search engine to extract no-goods up to a depth limit of 128.
The larger the depth limit, the more no-goods can of course be extracted. However, this comes at a cost:
Gecode’s search engines use an optimization that is called LAO (last alternative optimization, see also Last alternative optimization). LAO saves space by avoiding to store choices on the search engine’s stack when the last alternative of a choice is being explored. But no-goods can only be extracted if LAO is disabled as the last alternatives are required for the computation of no-goods. LAO is automatically disabled for the part of the search tree with a depth less than the no-goods depth limit. That is, an engine requires more memory during search with a larger depth limit. This can pose an issue for very deep search trees.
What also becomes clear from this discussion is that the peak search depth reported by a search engine increases with an increased depth limit.
It is easy to see that no-goods get longer (with more literals) with increasing search tree depth. The larger a no-good gets, the less useful it gets: the likelihood that all literals but one are subsumed but not failed (which is required for propagation) decreases.
When the no-goods are posted, a single propagator for all no-goods is created. This propagator requires \(O(n)\) memory for \(n\) no-good literals. Hence, increasing the depth limit also increases the memory required by the propagator.
No-goods from solutions restarts. The master() function shown above posts no-goods even when the restart meta search engine has found a solution. When the engine continues this means that the same solution might not be found again as it has been excluded by a no-good. The situation is even slightly more complicated: the solution might not be excluded if it has been found at a depth that exceeds the no-good depth limit.
If no-goods should not be posted when a solution has been found, the master() function can be redefined as:
virtual bool master(const MetaInfo& mi) {
  ...
  if (mi.solution() == 0)
    mi.nogoods().post(*this);
  ...
}
Limitations. Not all branchers support the generation of no-goods. In that case the longest sequence of no-goods starting from the root of the search tree up to the first choice that belongs to a brancher that does not support no-goods is used.
All pre-defined branchers for integer, Boolean, and set variables support no-goods unless user-defined commit functions are used (see User-defined value selection). Branchers for float variables and branchers for executing code (see Executing code between branchers) do not support no-goods.
No-goods and parallel search. The reason why after a restart no-goods can be extracted is because search computed the no-goods by exploring entire failed subtrees during search. This might not be true during parallel search. While parallel search engines also support the extraction of no-goods, the number of no-goods that can be extracted tend to be rather small.
9.7. Tracing search
The execution of search engines can be traced, where all important events of a search engine can be recorded and processed by a search tracer. A search tracer is implemented by a subclass of SearchTracer where several virtual member functions must be implemented that are called when a corresponding event occurs:
A single init-event occurs when the initialization of a search engine together with all of its components such as sub-engines and workers is complete. See below for more details about sub-engines and workers.
A single done-event occurs when all components (workers) of a search engine have been deleted.
Each time a new node of the search tree is created, a node-event occurs that provides information about the newly created node and the edge leading to it (unless it is the root node).
Some search engines perform several rounds: each time a new round starts, a round-event occurs. Restart-based search (RBS) starts a new round by performing a restart (see Restart-based search) and limited-discrepancy search (LDS) starts a new round for each probe with a different discrepancy.
Some search engines might skip edges, in these cases a skip-event is generated. See below for more details.
Search tracers.
...
class SimpleSearchTracer : public SearchTracer {
protected:
  static const char* t2s(EngineType et)  {
    ...
  }
public:
  SimpleSearchTracer(void) {}
  // [example search tracer:init]
  // [example search tracer:node]
  // [example search tracer:round]
  // [example search tracer:skip]
  // [example search tracer:done]
  virtual ~SimpleSearchTracer(void) {}
};
A simple search tracer printing information to std::cout is shown in Program 9.3. A similar search tracer is defined by the class StdSearchTracer.
As mentioned above, all events correspond to virtual member functions that are called when an event occurs. The member functions are executed in mutual exclusion as the events might occur in parallel from search engines using multiple workers (threads).
Defining a search tracer. A search tracer can be defined as part of the search options (see Search options). For example, if t is a search tracer, then creating a depth-first search engine using the tracer t can be done as follows:
Search::Options o;
o.tracer = t;
DFS<Script> e(s,o);
Init-event. After the search engine(s) have completed their initialization, the member function init() is called. The class SearchTracer provides member functions with which the configuration of the search engine can be inspected. Search engines are identified by engine identifiers of type unsigned int.
The root engine has always the identifier 0U. Meta engines such as restart-based search (RBS) and portfolio-based search (PBS) have sub engines whereas non-meta engines have workers that perform the actual exploration of the search tree. The following code:
  virtual void init(void) {
    std::cout << "trace<Search>::init()" << std::endl;
    for (unsigned int e=0U; e<engines(); e++) {
      std::cout << "\t" << e << ": "
                << t2s(engine(e).type());
      if (engine(e).meta()) {
        // [example search tracer:init for meta engines]
      } else {
        // [example search tracer:init for engines]
      }
      std::cout << "}" << std::endl;
    }
  }
lists all engines together with their engine identifiers starting with the root engine (the member function engines() returns the number of engines). Information about an engine is provided by the member function engine() which takes an engine identifier and returns a reference to an object of type SearchTracer::EngineInfo providing information about an engine.
For simple engines (that is, non-meta engines) such as depth-first (DFS), branch-and-bound (BAB), and limited-discrepancy search (LDS), the following code prints information about their workers:
        std::cout << ", workers: {";
        for (unsigned int i=engine(e).wfst(); i<engine(e).wlst(); i++) {
          std::cout << i; if (i+1 < engine(e).wlst()) std::cout << ",";
        }
An engine of type AOE (for any other engine) is an engine that Gecode creates in certain situations if the root of the search tree is already known to be failed.
For meta engines, the following code prints information about their sub-engines:
        std::cout << ", engines: {";
        for (unsigned int i=engine(e).efst(); i<engine(e).elst(); i++) {
          std::cout << i; if (i+1 < engine(e).elst()) std::cout << ",";
        }
For example, for a branch-and-bound engine with a single worker (using a single thread), the init() function prints:
0: BAB, workers: {0}
For a branch-and-bound engine with four workers (using four threads), the init() function prints:
trace<Search>::init()
	0: DFS, workers: {0,1,2,3}
For a restart-based search engine using a depth-first engine with a single worker (using a single thread), the init() function prints:
trace<Search>::init()
	0: RBS, engines: {1}
	1: DFS, workers: {0}
For a portfolio-based search engines with two depth-first search engines as assets using four threads, the init() function prints:
trace<Search>::init()
	0: PBS, engines: {1,2}
	1: DFS, workers: {0,1}
	2: DFS, workers: {2,3}
Note that assets can be also restart-based search engines.
Node-events.
  virtual void node(const EdgeInfo& ei, const NodeInfo& ni) {
    std::cout << "trace<Search>::node(";
    switch (ni.type()) {
    ...
    case NodeType::BRANCH:
      std::cout << "BRANCH(" << ni.choice().alternatives() << ")";
      break;
    }
    std::cout << ',' << "w:" << ni.wid() << ','
              << "n:" << ni.nid() << ')';
    if (ei) {
      if (ei.wid() != ni.wid())
        std::cout << " [stolen from w:" << ei.wid() << "]";
      std::cout << std::endl << '\t' << ei.string()
                << std::endl;
    } else {
      std::cout << std::endl;
    }
  }
The virtual member function called for a node-event takes information about an edge of type SearchTracer::EdgeInfo and a node of type SearchTracer::NodeInfo as input. The code shown in Program 9.4 prints the type of the node. It then prints information about the worker identifier (ni.wid()) and node identifier (ni.nid()). Both worker and node identifiers are of type unsigned int. Note that the edge also has information about the parent node of the current node and which worker created it. In case the edge does not exist (that is, the test ei is false), the node is in fact the root node of the search tree. The string printed is the output printed by the brancher corresponding to the edge (see Using variable-value print functions for more information).
Note that the node identifiers are unique per worker. As the number of workers is available with the workers() member function, the numbers can be made easily unique globally.
Round-events. A round-event is generated either before a restart by a restart-based search engine or when a limited-discrepancy search engine starts a new probe with an increased discrepancy. The information passed to the round() member function is the engine identifier corresponding to the engine starting a new round:
  virtual void round(unsigned int eid) {
    std::cout << "trace<Search>::round(e:" << eid << ")" << std::endl;
  }
Note that the node identifiers are not reset at a round-event.
Skip-events. A skip event occurs when a worker decides that a certain node does not need to be explored. This can happen for branch-and-bound search engines where an entire subtree is pruned or for limited discrepancy search where a solution is omitted as it had already been found during a previous probe with a smaller discrepancy limit. The information provided to the skip() member function is of type SearchTracer::EdgeInfo:
  virtual void skip(const EdgeInfo& ei) {
    std::cout << "trace<Search>Search::skip(w:" << ei.wid()
              << ",n:" << ei.nid()
              << ",a:" << ei.alternative() << ")" << std::endl;
  }
Done-event. The done event is executed if all workers have terminated. Here it just prints this fact:
  virtual void done(void) {
    std::cout << "trace<Search>::done()" << std::endl;
  }
Note that, however that the tracer is not deleted after a done event. This is the obligation of the user of the tracer.
9.8. Using the CPProfiler
The CPProfiler is a graphical tool for better understanding the search space of a problem [57]. It can be downloaded from github.com/cp-profiler.
Gecode can connect to an already running instance of the CPProfiler by means of creating a search tracer. The tracer then sends all search trace information to the respective instance of the CPProfiler, which then can use the trace information for visualization and analysis.
A search tracer to connect to a running CPProfiler instance can be created by creating an object of class CPProfilerSearchTracer as follows:
auto t = new CPProfilerSearchTracer(id,name,port,gi);
where id (an integer) defines the execution identifier to be displayed by the CPProfiler, name (a string of type std::string) defines the name displayed by the CPProfiler, port (an unsigned integer) defines the network port used by the CPProfiler, and gi is a pointer to an object of class CPProfilerSearchTracer::GetInfo for information about a search tree to be displayed by the CPProfiler. The arguments for port and gi are optional, the default for port is defined by Search::Config::cpprofiler_port (currently 6565) and the default for gi is nullptr.
Note that commandline support for the CPProfiler is provided, see Commandline options. There are options to specify the execution identifier, the port, and whether default information about nodes in the search tree should be transferred to the CPProfiler.
An object that determines which information about a search tree node should be displayed when the node is inspected in the CPProfiler, can be defined by inheriting from the class CPProfilerSearchTracer::GetInfo and defining the virtual member function:
virtual std::string getInfo(const Space& home) const;
that must return an information string of type std::string for the search tree node home.